Find the relevant memory
Match the parent domain and book topic using their names and descriptions. Use multiple child tags to select the relevant facets, then read the matching conclusions and evidence.
SIDERA batch processing · One-off purchase
SIDERA Memory turns supported Claude, Codex, Grok and Gemini session logs into reusable project memory. Recover decisions, reasons and unfinished work across sessions and models.
Receive structured memory.md and losslessly compressed original logs, with dated evidence and source references.
This store sells one-off SIDERA batch processing. You can purchase it without ShadowHarness. ShadowHarness includes SIDERA and automatic recall; the prices here cover this separate batch service.
x402 ordering · USDC on Base, Polygon or Solana.
An isolated container for every order. Private downloads. Data handling and retention.
Recover completed work, decisions and open questions together.
Carry reasoning and constraints into the next task or agent handoff.
Ground recall in dated conversations and traceable original evidence.
Supported Claude, Codex,
Grok & Gemini JSONL logs
Topics, decisions, unfinished work and the conversations that support them.
All submitted original logs, compressed losslessly. Original bytes preserved.
Read the product
Published on 14 September 2026 from 20 session logs prepared for publication. The 12,225,846-byte input cost 0.26 USDC to process.
A question for the next agent
What the memory answers
Search tnef. The section dated 2 September 2026 identifies an Outlook TNEF container holding one PDF. The later confirmation compares it with the separate PDF and records that their bytes match. The email attachment recovery topic links back to 28 July.
### この会話で確認した内容
`noname (1)` は実行ファイルではなく、Outlook由来のTNEF(winmail.dat相当)コンテナであり、中に `御見積~2.PDF` が1件入っているだけだと確認できた。
This is an edited public sample. The archive restores the submitted input byte for byte. The sample notes document source verification and publication details.
Memory you can check
The hard part is maintaining a coherent concept structure across large logs and limited context windows. Sidera connects conclusions to parent and book labels, descriptions and multiple child tags, giving your agent a structure for retrieving the right evidence.
Match the parent domain and book topic using their names and descriptions. Use multiple child tags to select the relevant facets, then read the matching conclusions and evidence.
Retrieve matching conclusions by their conversation dates, newest first. Follow recorded changes while keeping unfinished work visible. Topic dates help trace the subject’s history.
Source references identify a log file and an exact byte range. Extract raw.tar.zst and use the included archive reader to retrieve that passage from the preserved original logs.
Use the batch output with your own retrieval workflow: topic relationships, tags and dates support lightweight structured RAG. The recall implementation guide explains how to connect it. ShadowHarness includes SIDERA and automatic recall.
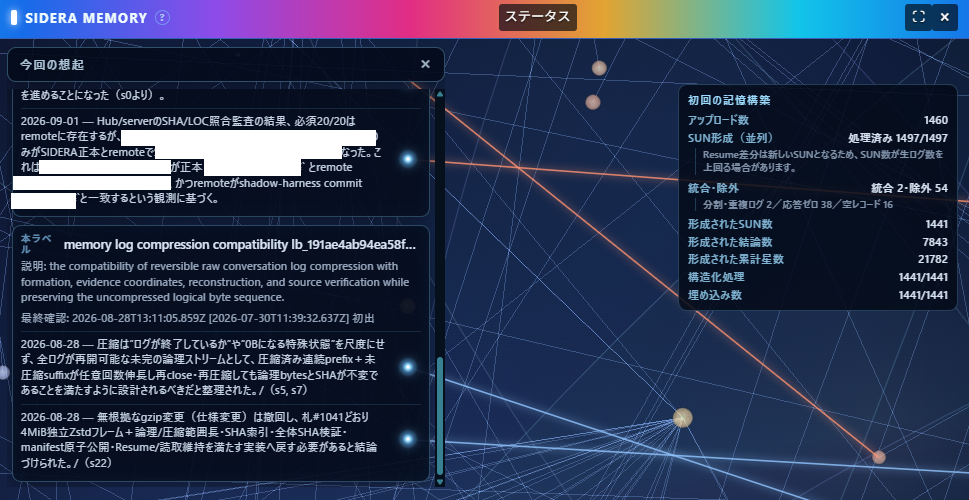
The developer’s own environment spans 1,441 formed session units, 7,843 conclusions and 21,782 source-linked records, organized under 1,281 parent/topic labels. See the developer’s environment and label consistency.
For richer recall, embed label descriptions while keeping parent/book relationships, child tags and dates as metadata. Use them in RAG or structured RAG; when an older passage matches, also retrieve the latest conclusions for its topic. For large local files, an index and a reader such as Rust’s memmap2 can supply selected MD ranges. The usage guide explains these methods, including how to build your own index.
One-off SIDERA batch service
These are one-off log processing fees, separate from ShadowHarness pricing. ShadowHarness includes SIDERA and automatic recall. This store sells batch processing of your collected logs as a separate service.
Standard rates are 0.020 USDC per MB, falling to 0.018 at 1 GB and 0.015 at 5 GB. The reached rate applies to the whole order.
Get a free quote before paying. Status checks and completed-file downloads require no additional payment.
| Original logs | USDC | Processing |
|---|---|---|
| 1 MB | 0.02 | 15–30 minutes |
| 100 MB | 2 | 15–30 minutes |
| 500 MB | 10 | 1–2 hours |
| 1 GB | 18 | 2–4 hours |
| 2 GB | 36 | 4–8 hours |
| 5 GB | 75 | 10–20 hours |
Logs that require more work to interpret content and organize decisions, changes and their relationships may receive a higher quote. Your quote explains any increase above the standard guide and states the final price before you pay. Processing times are typical ranges; upload time is separate.
1 MB = 1,000,000 bytes; 1 GB = 1,000 MB. We measure original log bytes and round the whole order up once to the next MB. Compression does not change the price. These are example volumes, not minimum or maximum order sizes.
A purchase decision for your agent
Use this batch to compile one project’s results, reasons, changed decisions and unfinished work at a milestone, handoff or resumption.
Even after an agent removes 95% of a 500 MB history locally, producing and checking the structured record can become a $1,000-class GPT-6 Astra job under the explicit assumptions below.
Read the 12-question cost argument ↗| Processing route | Cost |
|---|---|
| Sidera batch | 10 USDC |
| Astra Standard scenario | $1,001.39 |
| Astra Batch/Flex, same usage | $500.70 |
Illustrative scenario: 25 MB retained input; 28.57 MB final artifact extrapolated from a measurement recorded on 13 September 2026; 2.5 bytes/token; full model generation of the artifact; uncached requests of at most 272K input tokens each. Extra context, intermediate output and reasoning are assumed budgets.
Astra Standard: $10/M input and $50/M output, including reasoning. Batch/Flex: 50% of those rates. At 1 USDC = 1 USD, the difference from Sidera’s fee is $991.39 or $490.70 in these scenarios. Prices checked 13 September 2026. Official rates and limits.
A processing measurement recorded on 13 September 2026 used 53,206,231 input bytes and produced 3,040,176 bytes of memory.md. Applying that measured ratio to 500 MB gives a 28.57 MB artifact. At 2.5 bytes/token, generating the final artifact alone costs $571.39 at Astra Standard rates. The public sample documents its separately measured delivery.
10M tokens of initial input + 5M of additional context and selected checks + 11.4278946M of final output + 2.6M of intermediate and other output + 3M of reasoning = $1,001.39. Local copying, selective retrieval and cache hits can reduce the model bill; the sourced calculation shows how to substitute your agent’s workflow.
Reading the 25 MB retained history and 28.57 MB candidate artifact once adds $214.28 in Standard input alone at 2.5 bytes/token. A short verdict can require substantial context. That full pass is additional to the selected checks above, before further reasoning or repairs.
Preserving information, chronology, corrections and source evidence across a 500 MB history also requires algorithm design, experiments and evaluation. The public sample and usage guide show the structured output and source links an alternative needs to reproduce. Budget that development separately from processing a single batch.
Everyday operating scale: SIDERA routinely handles several gigabytes of raw logs. Development test datasets have a median size of at least 3 GB, making the 500 MB example a modest batch within the developer’s everyday operating scale.
For autonomous agents
Choose your Claude, Codex, Grok or Gemini sessions. The purchase client carries your free estimate through one order, a formal quote and verified delivery.
On macOS, Windows or Linux, run the Node.js 22.23.1+ client to check native conversation logs and create one archive locally. The client guide provides installation, wallet connection and commands; the preparation guide lists log locations and supported formats.
memory.md and raw.tar.zst.Existing conversation records. Sidera processes the raw logs you choose to upload from past conversations with LLM tools. It organizes the existing record of those interactions into reusable memory. Personal information in the logs is used only to produce and deliver your order and to provide the recovery described below.
Partial use of U.S. models. Some structuring steps use models developed by U.S. companies (excluding xAI). Text needed for these steps is sent to their AI APIs for processing with model-training use disabled.
Isolation and access. Each order runs in an isolated container. Uploads and downloads use HTTPS, and access to your order data and completed files requires your private order token. Other customers cannot access your order.
Retention and recovery. Download and acknowledge within 24 hours after processing completes. The used worker is deleted after delivery acknowledgement or at the end of that window, once the deliverables have been verified for recovery. Recovery data is kept for seven days and then permanently deleted. Recovery requires an email from the same address used for the order and the exact order ID.
You may replace personal or confidential information with dummy text or numbers before uploading. Preserve the supported CLI log structure and field formats.
If you edit logs before uploading, the quote is assessed from the submitted content. Removing material does not guarantee a proportionally lower price. Review the final amount before paying; it is fixed when you pay.
After payment, customer-requested cancellations are not accepted because processing costs are incurred from the start.
If log formatting fails and no deliverables can be produced, we will refund the processing payment. You do not need to retry processing.
The usage guide explains how to read the memory, compare dates and check source references.